Ask a chatbot for the title of a colleague’s PhD thesis. It may give you three different answers, one after another, all in the same calm voice. None of them correct. OpenAI’s researchers used almost exactly this example in a 2025 post on why language models hallucinate.
The example is useful because nothing in it looks broken. The answer has a title, a university, a year. It reads like a fact. That is the real teaching problem. Students are rarely fooled by nonsense. They are fooled by things that sound right.
Why “plausible” is the hard part
A language model learns from huge amounts of fluent text. Some things can be predicted from patterns, like spelling, grammar and how a polite email starts. Others cannot. A birthday, a citation or the title of one person’s thesis is an arbitrary fact, and there is no pattern to learn it from.
What the source says
Kalai and colleagues argue that models hallucinate because training and evaluation procedures “reward guessing over acknowledging uncertainty.” Their illustration: if a model does not know someone’s birthday and guesses “September 10,” it has a 1-in-365 chance of being right. Saying “I don’t know” scores zero. So on many test scores, a guesser looks better than an honest model.
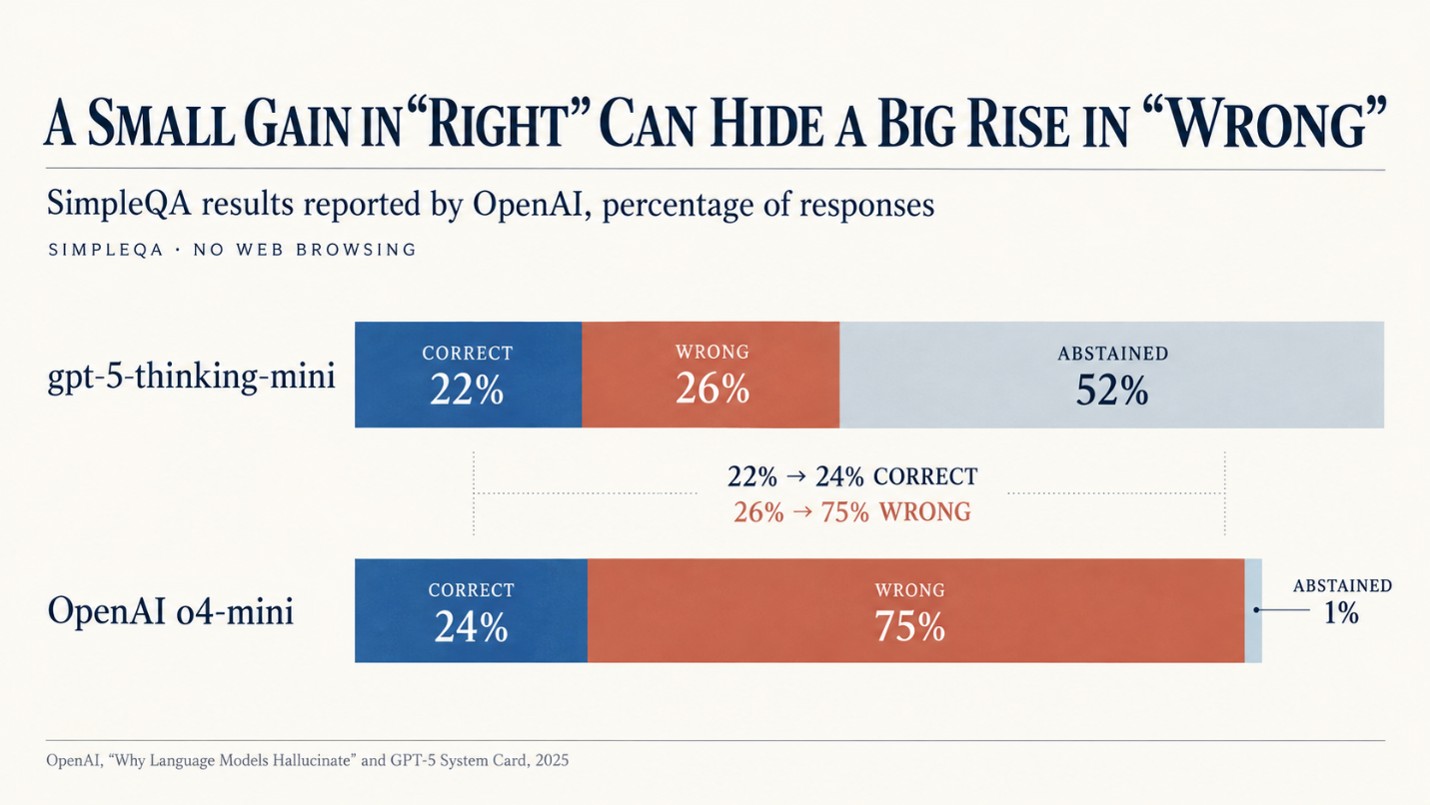
OpenAI’s post also compares two models on one benchmark, SimpleQA. This is what it reports:
- gpt-5-thinking-mini: abstained on 52% of questions, was right on 22%, wrong on 26%.
- o4-mini: abstained on 1%, was right on 24%, wrong on 75%.
This is one benchmark and OpenAI’s own models. It shows the incentive problem. It is not a general error rate for AI tools.
A confident tone is not evidence. Often it is just what the system was rewarded for. That is a lesson students can grasp, and it changes how they read every AI answer.
Teach the mechanism first, then the habit
“Always check your sources” is fair advice that students tend to ignore, because it does not tell them when to worry. A student who knows that a model predicts likely text can work out for themselves that a citation is risky and a grammar fix is not.
The EU-OECD AI Literacy Framework for primary and secondary education (published June 2026) describes AI literacy as knowledge, skills and attitudes that let learners understand how AI systems work, evaluate their outputs critically, and use them ethically and creatively. In our reading, understanding comes before evaluating. The framework does not prescribe a lesson order, so treat that as our view.
Here is a simple routine students can use on any AI claim. It is our suggestion and is not taken from either source.
| Question | What students do | Why it works |
| Can this be checked? | Find the names, dates or titles in the claim and look for a primary source | Made-up facts often look very specific |
| What would the model have to know? | Decide if it is a pattern (grammar, common knowledge) or an arbitrary fact (a citation, a date) | Arbitrary facts cannot be predicted from patterns |
| Does it give the same answer twice? | Ask the same thing three different ways and compare | Different confident answers suggest guessing |
| Who benefits if I believe it? | Check the source, purpose and what is left out | Connects to ethics and bias |
What school leaders can look for
Not a ban, and not a warning poster. Look for tasks where students verify one AI claim against a primary source and report what they found. Look for lessons where they explain why a wrong answer looked believable. And look for classrooms where “I don’t know” from an AI counts as a good answer.
This connects naturally to deepfakes in the classroom, to how generative AI actually works, and to critical thinking skills for an AI-saturated world.
Something to think about:
If students only catch an AI error when the answer looks odd, what will they do when it looks perfect?
How do we assess this?
Ask students to verify one AI claim and report their method and result. Then ask them to explain why the error looked believable. The second task shows whether they understand the mechanism.
Where Scholario APEX AI teaches the limits next to the tool
In the Scholario APEX AI curriculum, this work sits in Grade 8, the Natural Language Processing and Generative AI unit. Students learn how text becomes numbers (tokenisation and word embeddings) and how attention works. In the same unit they study the limits: hallucination, bias and the absence of genuine understanding, plus responsible use with citation. One stated outcome is that students can identify three limitations of large language models. The digital set includes a Responsible GenAI Evaluation Task, and the unit ends with an NLP evaluation and reflection capstone.
The idea does not begin at Grade 8. Grade 1 already teaches what AI cannot do, and Grade 11 returns to hallucination and robustness through a governance lens. This is also covered in AI safety in a school curriculum.
FAQs
Is “check your sources” enough for students?
Not on its own. It does not tell students when to be suspicious. Knowing why models guess gives them a reason to check the risky parts first: names, dates and citations.
How early can this start?
Young students can learn that AI makes mistakes and has limits. The mechanism (text as numbers, predicting likely text) suits secondary students. In the APEX documents, “what AI cannot do” appears in Grade 1, and hallucination is taught explicitly in Grade 8.
Will better models make this lesson unnecessary?
I don’t know. The OpenAI paper argues the problem can be reduced by changing how models are scored, and it says arbitrary facts cannot be predicted from patterns alone. Schools should plan for students meeting confident, wrong answers for some time.